
Documents into data you can trust.
Two production systems: DocuLens AI reads invoices and contracts into typed, validated fields and scores them deterministically; the OCR & Speech Workspace turns scans and speech into searchable, citable knowledge.
- Extraction
- Strict output schemas, every field checked
- Scoring
- Deterministic: same input, same score
- OCR
- Concurrent, page-batched PDFs
- Speech
- Live transcription, chat with citations
Two systems
Built for finance, legal and operations teams who need answers they can audit.
DocuLens AI
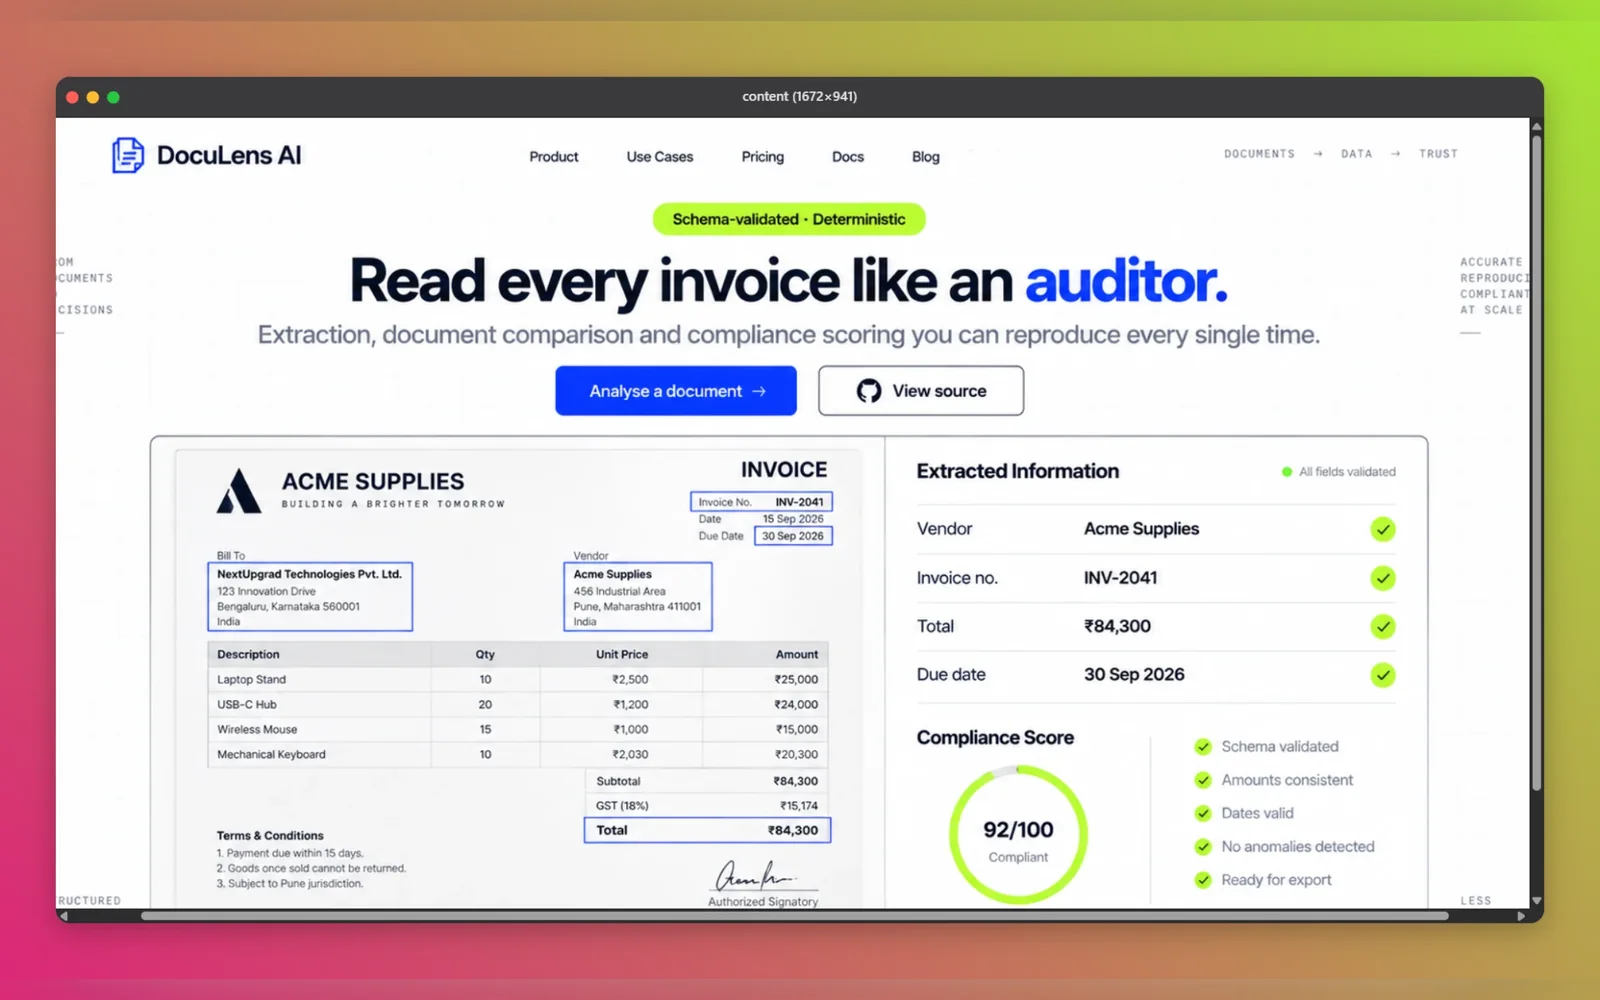
Groq-hosted models extract invoices and contracts into schema-validated data. Two documents diff field by field. Each is scored against a compliance rule-set with deterministic scoring, which is what finance and legal teams need.
OCR & Speech Workspace
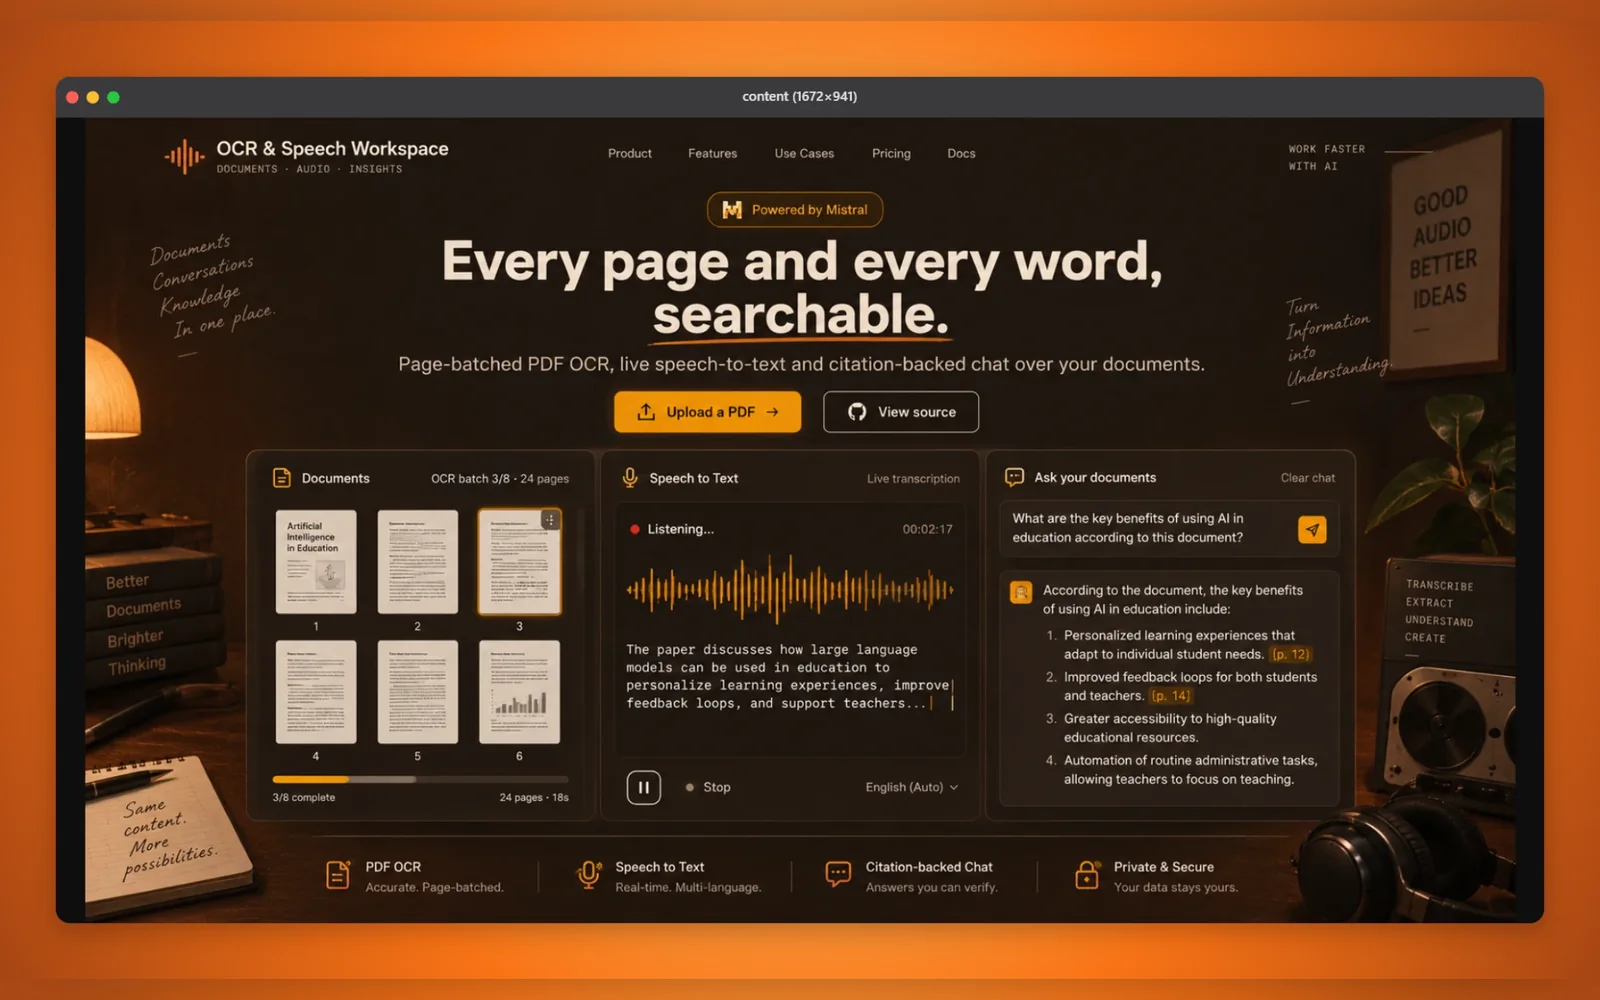
Large PDFs are OCR'd concurrently in page batches, speech is transcribed live, and every document becomes a scoped knowledge base. Answers cite the exact pages they came from.
Principles
What makes document AI dependable rather than impressive.
- 01
Schemas before prompts
Every extracted field is typed and validated before it is trusted. A model's free text never reaches the database.
- 02
Determinism where money is involved
Compliance scores are computed, not generated, so the same document always scores the same.
- 03
Citations by page
A transcript or a scan stays verifiable when every answer points back to the page it came from.
Gallery
The two products.
Have documents that need to become data?
Invoices, contracts, scans, recordings. Tell me what they are and what must be true about the output.