
Face recognition is matching vectors, not photos.
Face recognition finds a face, aligns it, turns it into a compact embedding and compares that vector with stored ones; a close match is the same person. Detection asks 'is there a face', recognition 'whose face', and liveness 'is this a real person or a photo'. In FaceVision all of this runs in the browser and only the embedding is stored.
- Pipeline
- Detect, align, embed, compare
- Detection vs recognition
- Find a face vs identify it
- Liveness
- Blocks photos, screens and masks
- I built
- FaceVision: browser-side, embeddings only

- 5production AI apps
- 14engineers led
- 200+students mentored
Questions students ask
The face recognition questions searched most, answered from shipping it.
What is face recognition?
Face recognition is identifying or verifying a person from their face. Verification asks whether this face matches a specific claimed identity (unlocking your phone); identification asks which of many enrolled people this face belongs to (an attendance system). Both rest on the same mechanism: a neural network maps a face image to an embedding, a vector of a few hundred numbers, trained so that images of the same person land close together and different people land far apart. Matching is then a distance comparison with a threshold, not a comparison of photos.
How does face recognition work?
- Detection: a detector finds faces in the frame and returns boxes and landmark points (eyes, nose, mouth corners).
- Alignment: the face is rotated and cropped using the landmarks so eyes and mouth sit in standard positions; this removes pose variation.
- Embedding: a recognition network (trained on millions of faces with a loss that separates identities) converts the aligned crop into a vector.
- Enrolment: a person's embedding, often an average of several captures, is stored with their identity.
- Matching: a new embedding is compared with stored ones by cosine similarity; above a threshold it is a match.
- Decision policy: thresholds tuned on your own data to balance false accepts and false rejects; liveness checked before any of this counts.
Face detection vs face recognition
Detection locates faces: it answers how many faces there are and where, with no idea who they belong to. A camera app's focus box and a crowd counter use detection only. Recognition goes further and identifies the face against enrolled identities. Detection is cheaper, needs no personal data, and runs on almost any device; recognition needs an enrolment database and carries privacy obligations, because an embedding of a face is biometric data under most laws. Build detection alone whenever the product only needs to know a face is present; add recognition only when identity is actually required.
What is liveness detection?
Liveness detection checks that the face in front of the camera belongs to a live person rather than a photo, a video on a screen, a printed mask or a deepfake. Passive liveness analyses a single frame or a short clip for texture, depth cues, reflections and screen patterns; active liveness asks the user to blink, turn their head or follow a dot, and checks the response. Without liveness, a recognition system can be unlocked with a picture from social media, which is the most common attack. Any face system used for access or attendance needs it; a demo that skips it is not a product.
Can face recognition be fooled by photo?
A recognition model on its own, yes. The embedding of a good photo of you held up to the camera is close to the embedding of your real face, because the model was trained to recognise faces, not to tell real from printed. That is exactly why liveness detection exists as a separate step. Systems with liveness reject flat photos and screens with high reliability; well-made 3D masks and injected video are harder and require stronger checks, depth sensors or challenge-response. When evaluating any face product, ask what it does about presentation attacks, and test it with a photo yourself.
How face recognition attendance system works
Each student or employee is enrolled once: several face captures, embeddings computed and averaged, stored against their ID with consent recorded. At the door or in a classroom, a camera stream runs detection on each frame, performs liveness checks, computes an embedding for each live face, matches it against the enrolled set, and logs attendance for matches above the threshold with a timestamp, while unknown faces are ignored or flagged. Good systems handle several faces per frame, avoid double-counting, work under varied lighting, and store embeddings rather than images. FaceVision runs this pipeline in the browser, so camera frames never leave the device.
How to face recognition in Python
Use a library that bundles detection, alignment and a pretrained embedding model: InsightFace, DeepFace or face_recognition (built on dlib) are the common choices. Load an image, detect faces, get embeddings for each, and compare with stored embeddings using cosine similarity. For enrolment, capture a few images per person and average their embeddings. Tune the match threshold on your own labelled pairs rather than taking the library default. For a live camera, read frames with OpenCV, run detection every frame and recognition every few frames to keep it fast. Add a liveness check before any match is acted on, and store only embeddings and consent records.
How OpenCV face detection works
OpenCV ships several detectors. The classic Haar cascade slides windows over the image at several scales and applies a cascade of simple rectangular feature tests trained to reject non-faces quickly; it is fast on CPUs and weak on angled or partially covered faces. The DNN module runs modern neural detectors (such as a compact single-shot detector or the YuNet model) that are far more accurate and still real-time on a laptop. The output in both cases is a list of boxes, with landmarks from the newer models, which you then pass to alignment and a recognition network. For anything beyond a demo, use the DNN detectors.
Why face recognition not working
- Lighting: strong backlight or deep shadow makes detection fail; add light or move the camera.
- Pose and distance: faces turned away or too small for the detector; set a minimum face size and ask the user to face the camera.
- Enrolment quality: one blurry capture gives a poor reference embedding; enrol with several clean captures.
- Threshold set wrong: too strict rejects real users, too loose matches strangers; tune on your own pairs.
- Changed appearance: glasses, masks, heavy beards shift embeddings; re-enrol or add captures.
- Camera or browser permissions: the stream never started; check permissions and the device selected.
- Model mismatch: embeddings from one model compared with another's; use one model for enrolment and matching.
- Liveness false rejects: a passive check failing on a low-quality webcam; adjust thresholds or add an active challenge.
What is face recognition used for?
Device unlock and app login; attendance and access control in schools, offices and events; identity verification during onboarding, paired with a document check; photo organisation that groups images by person; and finding a specific person in security footage, which is also where the hardest ethical questions sit. For any of these, the responsible design is the same: explicit consent, storing embeddings rather than images, on-device processing where possible, a liveness check, a tuned threshold with known error rates, and a way for people to be removed. That is the design FaceVision follows, and it is the design I recommend to every team that asks.
Build it responsibly
The checklist before a face system goes live.
- 01
Consent and minimal data
Record consent; store embeddings only; delete on request.
- 02
Liveness before matching
Passive check on every frame; active challenge for high-stakes actions.
- 03
Tune the threshold
Measure false accept and false reject rates on your own people and lighting.
- 04
Keep it on-device
Run detection, liveness and embedding in the browser or on the device; send vectors, never frames.
In the room
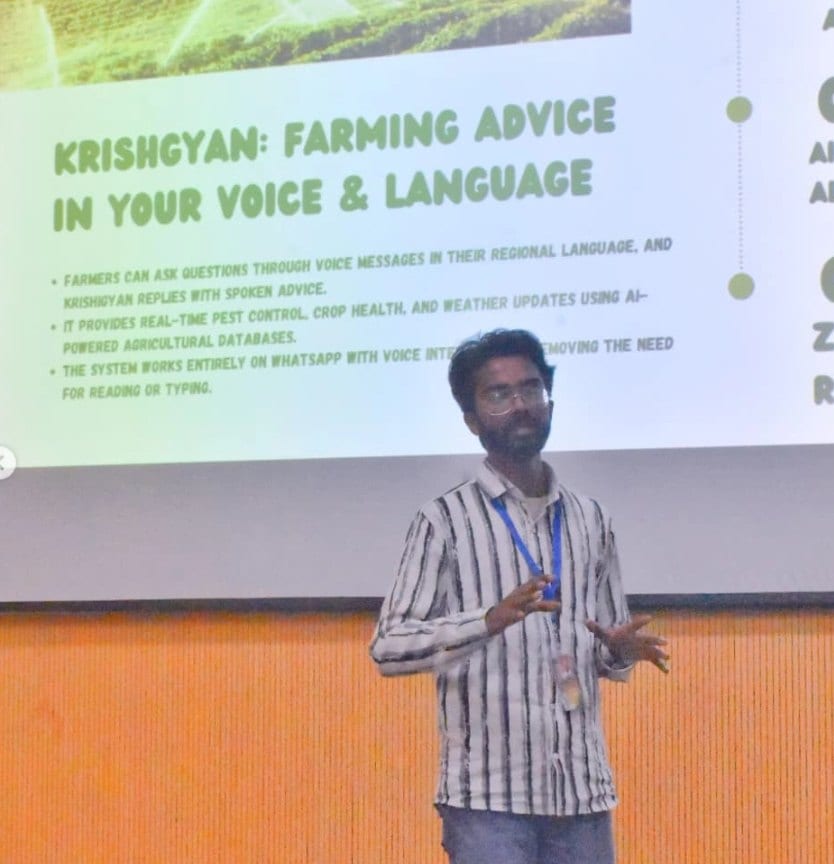
Where these systems get explained to students.
Read next
The vision fundamentals and privacy patterns behind this.
Face recognition that respects privacy?
I built one that never uploads a frame. I can build or review yours.