
YOLO: every object, every frame, in one look.
YOLO (You Only Look Once) is a family of object detectors that predict bounding boxes and classes for everything in an image in a single pass of a convolutional network, which is why it runs at video frame rates. Since 2016 it has gone through many versions from several groups. Training one on your own images takes an afternoon on a free GPU.
- Output
- Boxes, classes, confidences per image
- Speed
- Real time on a GPU; usable on CPUs and phones
- Versions
- Many since 2016; several active lineages
- Train on
- A folder of images and a labels file

- 5production AI apps
- 14engineers led
- 200+students mentored
Questions students ask
The YOLO questions searched most, answered from training and deploying detectors.
What is YOLO?
In computer vision YOLO is an object detection approach and the family of models built on it. Given an image it returns a list of detections, each a rectangle, a class label and a confidence, for every object of the classes it was trained on. It was designed for speed: rather than proposing candidate regions and classifying each, which earlier detectors did, it treats detection as a single regression from image pixels to boxes and classes. The name is also internet slang for 'you only live once', which is why searches mix the two; here it is the detector.
What does YOLO stand for?
You Only Look Once. The phrase describes the design: the network examines the whole image a single time and outputs all detections at once, instead of looking repeatedly at many candidate regions. The first paper, by Joseph Redmon and colleagues in 2016, used the name to contrast with two-stage detectors of the time. Later versions kept the name while changing almost everything underneath, so YOLO today means the lineage and the design philosophy, single-pass real-time detection, more than any one architecture.
What is YOLO algorithm?
The algorithm divides the image into a grid and makes each grid cell responsible for objects whose centre falls inside it. For each cell the network predicts a fixed number of boxes, each with position, size, an objectness score (is there an object here) and class probabilities. Training uses a loss that combines box position error, objectness error and classification error, with matching rules that decide which prediction is responsible for which ground-truth object. At inference, low-confidence boxes are discarded and overlapping boxes for the same object are merged by non-maximum suppression (or, in newer versions, avoided by design). The whole thing is one forward pass.
How does YOLO work?
A convolutional backbone extracts feature maps from the image at several resolutions, so both small and large objects are represented. A neck merges those scales so that each level has context from the others. A detection head reads the merged maps and, for every position, outputs box coordinates, objectness and class scores. Because the predictions are dense across the image, the network sees every region and its surroundings at once, which keeps it fast and reduces background mistakes. Post-processing turns the dense predictions into a clean list of detections. Modern versions add anchor-free heads, better losses and training tricks, but this pipeline is unchanged.
How does YOLO predict bounding boxes?
Each output position predicts a box relative to its location: an offset for the centre within the cell and a width and height, either as scaled anchors (predefined reference shapes, in older versions) or directly as distances to the box edges (anchor-free, in newer ones). The network outputs these as numbers that are transformed into pixel coordinates. During training, the loss compares predicted and true boxes with a measure of overlap such as IoU and its variants, which penalises both position and size errors, and objectness and class losses are added. Thousands of candidate boxes are predicted per image; confidence thresholds and suppression keep the few that matter.
How many YOLO versions are there?
More than a dozen numbered releases, from several groups. The original authors released versions one to three; other researchers continued with four and later numbers; Ultralytics released five, eight and eleven with a widely used training toolkit; and academic groups released six, seven, nine, ten and twelve, each with its own paper. Numbering is not a single lineage, and a higher number does not always mean better on your task. Newer releases generally improve accuracy per unit of compute and training convenience. Choose by the toolkit you want to use, the licence, and a quick test on your own images.
Which YOLO model is best for object detection?
Pick by constraints, then test. Each release ships in sizes (nano, small, medium, large, extra-large): the small sizes run on CPUs, phones and in browsers, the large ones give the highest accuracy on a GPU. For a student project or a quick product, a recent release from a well-maintained toolkit with a nano or small model is the pragmatic choice, because training, export and deployment are documented and work. Check the licence: some lineages use a copyleft licence that matters for commercial products, others are permissive. Then train two candidates on your data and compare mean average precision and speed on your hardware; your dataset decides.
What are YOLO models?
- Pretrained detectors: trained on the COCO dataset's 80 everyday classes, ready to run on people, vehicles, animals and common objects.
- Custom detectors: the same architecture fine-tuned on your labelled images for your classes.
- Task variants: segmentation (masks), pose (keypoints), oriented boxes, classification and tracking heads built on the same backbones.
- Sizes: nano to extra-large trade speed for accuracy.
- Exports: ONNX, TensorRT, CoreML and TensorFlow Lite versions for servers, phones, browsers and edge devices.
How to train object detection model
- Collect a few hundred images that look like your deployment conditions: same cameras, lighting and angles.
- Label boxes with a tool such as Label Studio, CVAT or Roboflow; export in the YOLO format (one text file per image with class and normalised box coordinates).
- Split into training, validation and test folders; write the small dataset config file listing paths and class names.
- Start from a pretrained checkpoint and fine-tune for tens of epochs with augmentation on; a free Colab GPU is enough for small models.
- Read the validation results: mean average precision per class, the confusion matrix, and the images with missed or false detections.
- Fix labels and add images where it fails; retrain; export to ONNX or the format your target device needs.
What is object detection in deep learning?
Object detection is the task of finding every instance of chosen classes in an image and localising each with a box, in contrast to classification, which labels the whole image, and segmentation, which labels every pixel. Deep learning solved it with convolutional networks that learn features and box regression together: two-stage detectors (region proposals then classification) and one-stage detectors (dense prediction in one pass, the YOLO family and others), with transformer-based detectors as a newer branch. Evaluation uses mean average precision over overlap thresholds. Detection is the foundation for counting, tracking, inspection and many of the products described across this site.
A detector in an afternoon
From photos to a running model on a free GPU.
- 01
Label two hundred images
Boxes for each class; consistent rules for edge cases; a validation split.
- 02
Fine-tune a small model
Pretrained weights, augmentation on, a few dozen epochs on Colab.
- 03
Read the misses
Confusion matrix and failure images; fix labels, add data, retrain.
- 04
Export and deploy
ONNX for the browser or server; quantize for phones and edge devices.
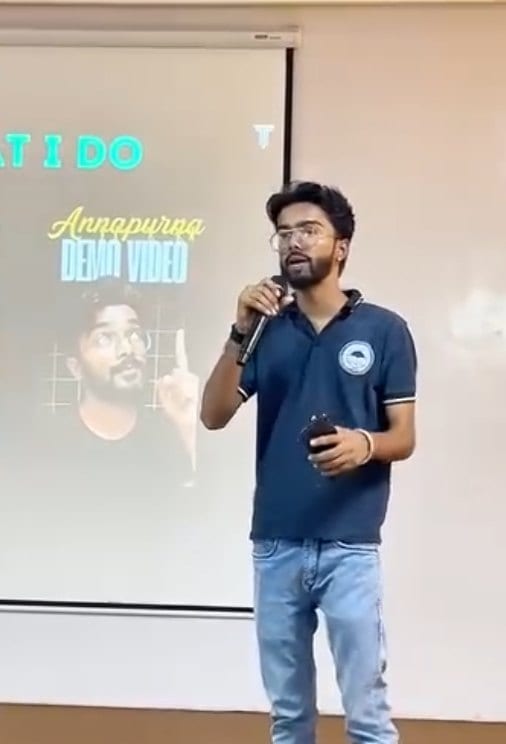
In the room
Where these systems get explained to students.

Read next
Vision fundamentals and deployment.
Need to find things in video?
I train detectors on your footage and deploy them where the camera is. Send me a sample.